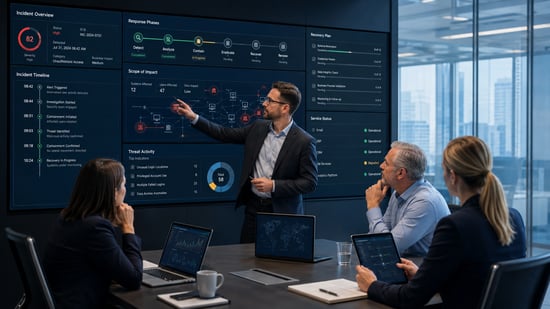
 Modern security systems can identify suspicious logins, unusual device behaviour, malware and other warning signs increasingly quickly. But an alert is not the same thing as a resolved incident.
Between detecting a problem and returning the business to normal sits a series of decisions. Is the alert genuine? How serious is it? What should be isolated? Who needs to know? Can operations continue safely? What has to be restored first? And how does the organisation know the threat has actually been removed?
For business leaders, this is the more useful way to think about incident response. The question is not simply whether the company has security tools. It is whether the organisation has the people, authority, information and support needed to turn a warning into an effective response.
Key Points: Turning Security Detection Into Business Response
A security alert creates value only when the organisation can validate it, decide what action is proportionate, coordinate the people involved and restore affected operations safely.
Key points include:
- Detection Is the Starting Point: Identifying suspicious activity does not mean the incident has been contained or resolved.
- Triage Determines Priority: The business needs to establish severity, scope and operational impact before deciding how aggressively to respond.
- Containment Has Consequences: Isolating accounts, devices or systems can reduce security risk while also disrupting legitimate operations.
- Automation Needs Boundaries: Predetermined containment actions can reduce delay, but material operational decisions may still require human judgement and authority.
- Response Capability Matters: Alerts need clear ownership, escalation arrangements and access to the expertise required to investigate and act.
- Recovery Follows Business Priorities: Restoring critical business functions safely matters more than simply bringing every affected system back online.
Proof Point: IBM's 2026 research associated extensive security AI and automation use with $1.93 million in breach-cost savings compared with organisations using none.
The Bottom Line: The strength of incident response is determined not only by how quickly a threat is detected, but by how effectively the organisation can move from warning to decision, containment and recovery.
What Happens After a Security Alert?
A security alert should start a process of validation, prioritisation and response rather than being treated as evidence that the problem has already been contained.
NIST's current incident-response guidance separates Detect, Respond and Recover within its Cybersecurity Framework. Detection involves finding and analysing potential incidents. Response concerns the actions taken after an incident is identified. Recovery focuses on restoring affected operations.
Its 2025 revision also places incident response within wider organisational risk management rather than treating it as an isolated technical function.
Once an alert appears credible, decisions can quickly extend beyond the security team. An account may need disabling. A device may need disconnecting. A system could have to be taken offline. Customers, suppliers, insurers or regulators may eventually need to be informed.
The technology can raise the alarm. The organisation still has to respond.
The First Job Is Establishing What the Alert Means
Not every security alert deserves the same reaction.
A failed login from an unfamiliar location is different from confirmed malware on a finance director's laptop. A suspicious email is different from evidence that an attacker has administrative access to several systems.
That makes triage one of the most important capabilities in the incident response process.
The organisation needs enough information to establish whether the alert is likely to represent a genuine incident, which users or systems may be affected, whether activity is continuing, how quickly the problem could spread and what business operations depend on the affected systems.
It also needs to know who has the expertise and authority to decide what happens next.
Speed matters, but speed without context can create another problem. Shutting down an important system may prevent an attack from spreading, while simultaneously interrupting customer service, payments, production or communications.
The goal is to choose the right intervention quickly enough to limit harm without creating unnecessary disruption.
Containment Can Create Business Trade-Offs
Containment is the point at which cybersecurity can become particularly visible to the wider business.
An affected endpoint might be isolated from the network. Credentials may be revoked. Remote access could be suspended. A server or application may need to be taken offline.
Those measures can reduce an attacker's room to operate, but some also affect legitimate users.
Imagine suspicious activity is detected within a system used by the sales team. Disconnecting it immediately may reduce the chance of further compromise, but it could also stop dozens of employees accessing customer information during a critical trading period.
There is rarely a universal answer. The appropriate action depends on factors such as the likely severity of the incident, the sensitivity of the data, alternative ways of working and the consequences of allowing the system to remain available.
Incident-response planning therefore needs to establish decision criteria before the organisation is under pressure.
Automation Can Shorten the Process, but It Does Not Remove It
Security automation is becoming increasingly capable.
Software can block suspicious activity, quarantine files, isolate endpoints, disable access or trigger investigation workflows without waiting for somebody to perform every task manually.
The financial evidence suggests these capabilities can matter. IBM's 2026 Cost of a Data Breach Report puts the global average cost of a breach at $4.99 million, 12% higher than the previous year. IBM also associated extensive use of security AI and automation with $1.93 million in breach-cost savings compared with organisations using none.
But automated controls still need clear incident-response processes, governance and decision boundaries.
As we explored when considering whether an organisation is ready for autonomous security, automation becomes more useful when the business has reliable data, clear ownership and sensible boundaries around what machines can do without approval.
NIST similarly recognises both automated and manual containment. Automated isolation may be exactly the right response to some events. At other times, an incident handler needs to choose a different action based on context that an automated system cannot fully understand.
The aim is to automate appropriate predetermined containment actions while retaining human judgement for decisions with material operational consequences.
Incident Response Capability Matters as Much as Detection Technology
A business can buy sophisticated monitoring technology and still have a weak incident response capability.
The critical question is: who does something when the technology finds a problem?
For an organisation with a substantial internal security team, the answer may be relatively straightforward. Smaller and growing businesses can have a more fragmented arrangement.
One person may maintain infrastructure. Another supplier may manage endpoints. A software vendor may monitor one part of the environment. Employees may report problems through a general helpdesk.
The weakness can emerge in the handoffs between them.
A useful incident response process should answer several practical questions. Who receives alerts? Who validates them? Who can escalate an incident? Who has permission to take action? And who remains accountable until the problem is resolved?
An alarm sitting unnoticed in a dashboard provides little protection. Likewise, identifying the correct response is of limited value if nobody has the access or authority to carry it out.
Where external support forms part of the arrangement, businesses should consider escalation arrangements and access to specialist expertise as well as basic availability. Organisations assessing that kind of capability could, for example, reach out to GroupOne IT, whose Sacramento offering includes managed services, security monitoring and different levels of technical support.
Whatever model a company uses, its incident response capability needs to match the incidents the organisation expects it to handle.
When an Incident Cannot Be Resolved Remotely
Much of modern IT support can be delivered remotely. During an incident, that means specialists may be able to investigate accounts, examine logs, isolate endpoints or change configurations without travelling to the affected location.
But remote access does not eliminate every physical dependency.
A failed network device may need replacing. A compromised laptop could need removing from circulation. Hardware may require reimaging or replacement. A server, cabling problem or local network failure may require somebody to work directly with the equipment.
Businesses should therefore know what happens when an incident cannot be resolved remotely.
Does the internal team take over? Does an external provider offer on-site coverage? Would another specialist be required? How quickly could somebody reach the affected location?
For example, El Paso organisations evaluating a combination of remote and local assistance can go to hardintech.com, where Hardin Technology describes both remote and on-site support among its services.
For leaders, the issue is knowing where remote response capability ends and what happens when physical intervention becomes necessary.
Ransomware Shows Why the Whole Process Matters
Ransomware illustrates the difference between detecting malicious activity and being able to manage its consequences.
An alert may arrive before encryption has spread widely, while an attacker still has access, or after several systems have already been affected. The appropriate priorities will differ in each case.
That is why ransomware readiness extends beyond protective technology. Businesses also need to understand critical systems, backup arrangements, escalation routes and alternative ways of operating before an incident occurs.
Preparation improves the quality of decisions made under pressure. Without it, an organisation can find itself trying to understand its own dependencies while the attack is still unfolding.
Recovery Is More Than Restoring a Backup
Containment stops the immediate problem from getting worse. Recovery has a different purpose: returning the organisation to a safe and usable operating state.
That does not necessarily mean restoring everything as quickly as possible.
Before affected systems return to production, the organisation needs confidence that the threat has been removed and that restoring the environment will not recreate the same problem.
Backups themselves may require checking. Credentials may need changing. Systems could need rebuilding or patching. Dependencies between applications also have to be considered.
NIST's current guidance emphasises validating restored assets and confirming that essential services are operating normally.
There is also a question of sequence.
A growing business may have dozens of systems but only a handful whose absence immediately prevents it operating. Knowing which should come back first is part of establishing sensible IT downtime recovery priorities.
This is where cybersecurity incident response and broader business continuity meet.
The objective is to restore the business functions that technology supports safely, rather than simply bringing technology back online.
The Incident Response Process Leaders Should Understand
Senior decision-makers do not need to know how every security product works. They do need confidence that somebody has answered the important organisational questions.
Before a serious alert occurs, leaders should know who receives warnings and who can determine whether they represent genuine incidents. They should understand which actions can occur automatically, who can authorise disruptive measures and when internal capability needs to be supplemented by an external specialist.
Recovery also needs ownership. Somebody should know which business functions take priority, how restored systems will be validated and what evidence is required before an incident can genuinely be regarded as closed.
The final question is what changes afterwards.
A resolved incident should improve future preparedness. That may mean changing access controls, updating escalation routes, correcting a technical weakness, improving recovery procedures or clarifying responsibilities that proved uncertain during the event.
These are governance questions as much as technical ones.
From Security Alert to Business Resilience
Businesses have more ways than ever to detect suspicious activity, and automation can increasingly take useful action before a human becomes involved.
That is progress. But detection technology is only one part of resilience.
The outcome of an incident depends on whether the warning is understood quickly, escalated appropriately, contained proportionately, supported by the right expertise and followed by controlled recovery.
For business leaders, that leaves a surprisingly simple question:
If an alert appeared today, would everyone who needs to act know what happens next?
Questions Business Leaders Ask About Cybersecurity Incident Response
What is the difference between cybersecurity detection and incident response?
Detection identifies activity that may indicate a security problem. Incident response begins when the organisation validates the problem and takes action to contain, investigate and remediate it. Recovery then focuses on restoring affected operations safely.
What are the main stages from a security alert to recovery?
At a business level, the sequence typically involves validating the alert, establishing its severity and scope, containing the problem, removing or addressing the cause, restoring affected operations, verifying that recovery is safe and reviewing what should change afterwards. The exact process varies according to the incident and the organisation.
Can security incidents be handled entirely through automation?
Some actions can be automated effectively, including blocking suspicious activity or isolating affected endpoints. However, incidents can involve business trade-offs, uncertain evidence and operational consequences that still require human judgement.
Why does incident response matter to business leaders?
A serious incident can affect system availability, employees, customers, suppliers, legal obligations and revenue. Leaders therefore need to understand responsibilities, escalation routes and decision authority even if they are not involved in the technical investigation.
What should a business review after a cybersecurity incident?
It should examine how the incident occurred, whether detection and escalation worked as intended, how effectively containment and recovery were handled, whether responsibilities were clear and what controls or processes should change before another event occurs.